ETL Migration - from legacy ETL to an open SQL ETL - {oa-tbx}
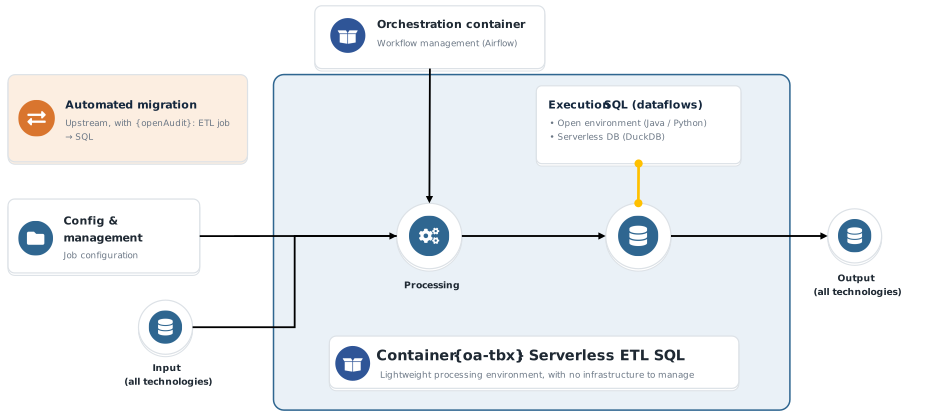
Once converted to SQL by {openAudit}, ETL processes run in the {oa-tbx} container, independently of the original ETL platform. {oa-tbx} runs SQL, Python, or Java processes, driven by configuration and orchestration repositories.
Principles
SQL is encapsulated in open containers, in ETL mode.
- Containers: transformations run inside an external container, {oa-tbx}, detached from the target database. Temporary containers act as intermediate storage areas where data is loaded before transformation. Jobs, and where relevant the data, are tested to guarantee integrity.
- Orchestration with Airflow: Airflow drives the execution of the containers, step by step; each transformation is defined as a job. The migrated scheduling automatically picks up all of the original instructions and scheduling logic.
Execution chain
The processes produced by {openAudit} are integrated into a configuration repository and a control repository used by {oa-tbx}, then orchestrated by tools such as Airflow or Dagster. Orchestration (dependencies, execution parameters, schedules, triggers) stays separate from the business logic, contained in the SQL scripts and dataflows.
Execution container
Dataflows can combine SQL, Python, Java, or other languages. The engine can rely on embedded databases such as DuckDB for certain intermediate processing steps.
Sources and targets
Input data comes from any technology accessible via SQL or JDBC; results are loaded into any system compatible with standard write mechanisms.
Benefits
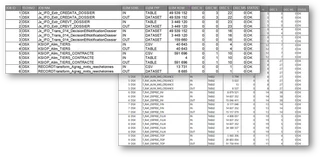
SQL pipelines are open and independent of proprietary Cloud platform runtimes. Across all migrated jobs (from a few thousand to more than 50 million rows), execution times are often counted in seconds, with an almost systematic OK status.
Governance and data lineage
{oa-tbx} keeps the complete trace between the original ETL logic and the executed SQL, at two levels of detail.
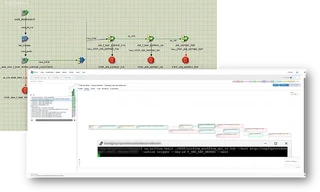
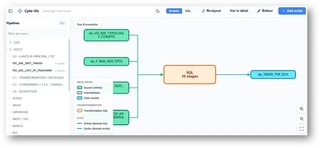
High-level pipeline view: only source and target tables are visible; intermediate ETL stages are grouped into a single SQL block, readable even for complex pipelines.
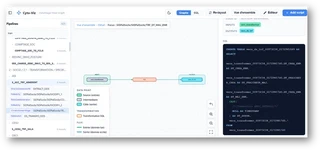
Detail on click for a transformation: clicking a stage (a Transformer, for example) displays its SQL equivalent, along with its inputs/outputs and its original metadata (type, stage ID).
Result: a SQL-based ETL/ELT chain, open and version-controllable, governed from the overview down to the executed SQL, regardless of the original ETL platform.