Data lineage - SaaS architecture
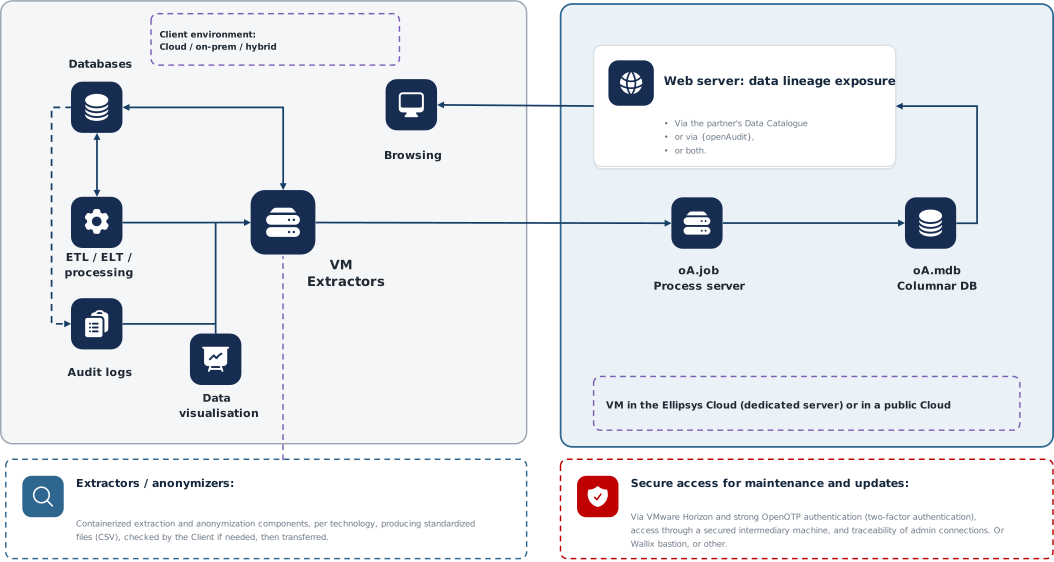
In a SaaS deployment, collection stays within the Client’s environment; processing, consolidation, and exposure are hosted on a dedicated infrastructure operated by Ellipsys.
Key point: only technical metadata is transferred, as CSV files that can be checked beforehand; business data is never used.
Metadata collection
Containerized extractors, one per technology, collect metadata from databases, ETL/ELT platforms, data visualization tools, and audit databases through dedicated service accounts; passwords are encrypted after first use. They produce standardized CSV files that the Client can check before transfer.
Audit logs can be anonymized by a dedicated container before being transferred.
Processing
The oA.Job server parses the metadata, reconstructs dependencies, consolidates technical objects, and integrates usage from audit logs. Results are stored in the oA.mdb repository (MonetDB, columnar database).
Exposure
Data lineage is available through the Mosaïc web portal, in third-party solutions (typically market data catalogs), or through the Client’s own integration mechanisms: collection and reconstruction are independent of exposure.
Overall flow mapping
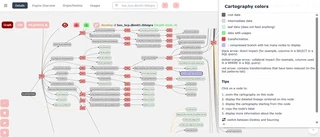
Mapping of dependencies between databases, ETL/ELT processes, and data usage.
Typical use case: impact analysis before modifying a technical object.
Usage analysis
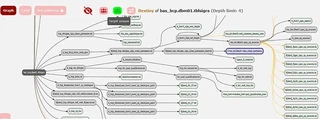
Cross-referencing data lineage with audit logs identifies the flows actually used, and therefore the dead branches.
Detailed data lineage
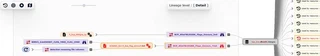
Navigation down to field level, transformation by transformation, from operational sources to usage.
Data lineage in dashboards
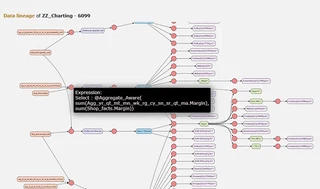
Traceability between source data, transformations, calculation rules, and reporting objects.
Typical use case: tracing the origin of a business indicator or validating a business rule.