Data lineage - on-premise architecture
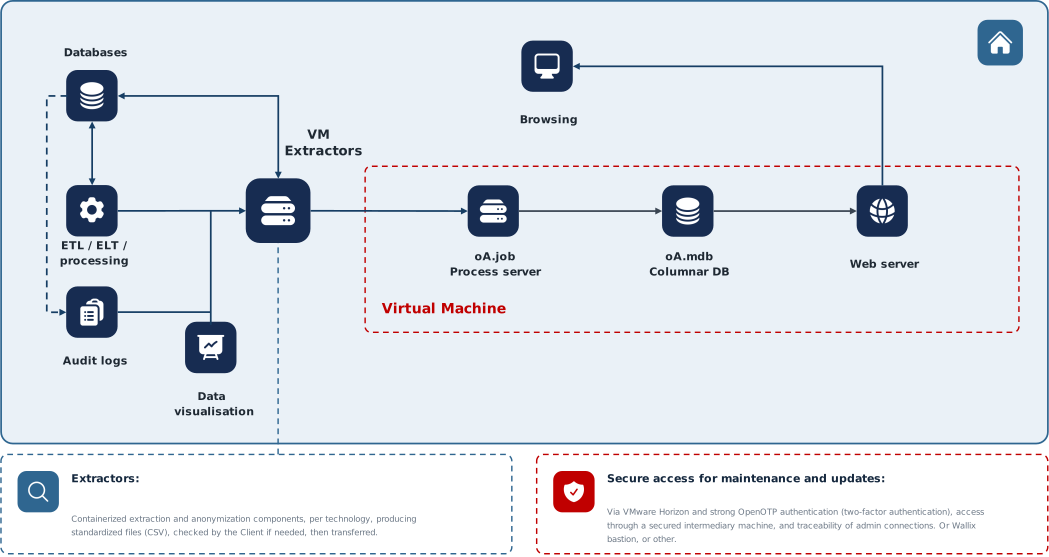
In the most security-sensitive environments (banking, insurance…), {openAudit} can be deployed directly at the Client’s site, on-premise or in a Cloud tenant of their choice, on a dedicated VM hosting data lineage collection, processing, and exposure.
Key point: processing, metadata, and repositories stay within the Client’s environment; no external SaaS component is required.
Metadata collection
Containers specialized by technology connect to databases, ETL/ELT platforms, data visualization tools, and audit databases through dedicated service accounts; passwords are encrypted after first use. They produce standardized CSV files that the Client can check before processing.
Audit logs, which may contain sensitive information, can be anonymized by a dedicated container before being integrated.
Processing
The oA.Job server parses and consolidates the metadata, which is stored in the oA.mdb columnar database (MonetDB). This very rich repository can be exported (dump) in the format the Client needs for specific analyses; queries are provided to explore it.
Exposure
Data lineage is available through the Mosaïc web portal, hosted on the VM. It can also feed a third-party solution, typically a data catalog.
Overall flow mapping
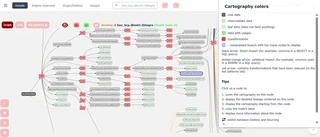
Automatic reconstruction of dependencies between databases, ETL/ELT processes, and usage in data visualization tools.
Typical use case: impact analysis before modifying a table or a business indicator.
Usage analysis
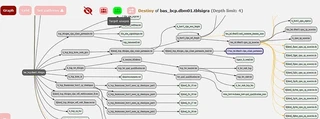
Cross-referencing data lineage with audit logs separates the objects actually used from unconsumed branches, and reveals simplification opportunities.
Detailed data lineage
Navigation down to field level, with direct access to the transformation code (drill through) to identify and fix an issue in a flow.
Data lineage in dashboards
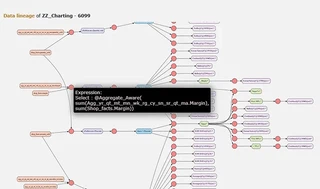
End-to-end traceability, from data feeds through business rules to the dashboard cell.
Typical use case: validating a business indicator or tracing the origin of a displayed value.