Data lineage - feeding third-party data catalogs to expose technical data lineage
{openAudit} exposes data lineage through its Mosaïc web portal, but the consolidated metadata can also be published to market data catalogs, which are often limited when it comes to data lineage. Governance teams can then work in a single tool.
Key point: collection, connection, and data lineage reconstruction stay in the {openAudit} technical repository, independent of the target catalog.
Architecture
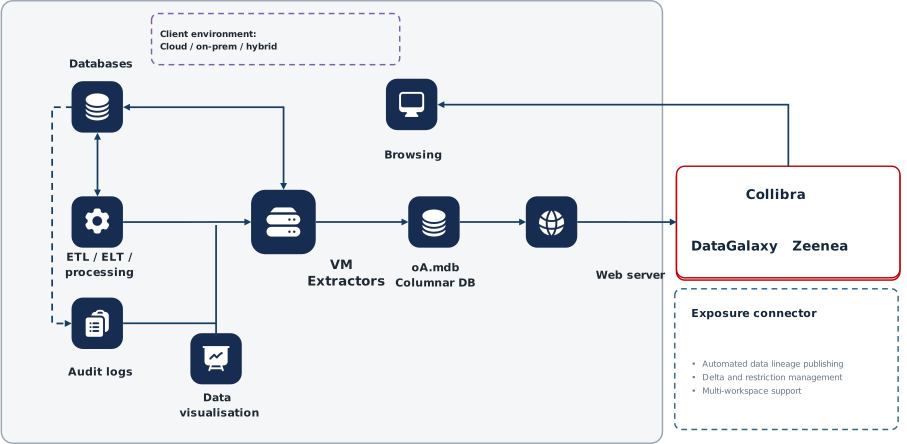
After processing by the oA.Job engine, metadata is consolidated in the oA.mdb columnar database: field-level data lineage, usage, and governance information where applicable. Catalogs are fed from this single repository through dedicated exposure connectors; they only consume this consolidated metadata, never the original technical sources.
Exposure connectors
The connectors handle automated data lineage publishing, continuous synchronization, restriction management, and support for multiple Workspaces. Exposure can be full or partial depending on the catalog’s display capabilities, while the data lineage produced upstream remains available at field level.
Catalogs supported to date: DataGalaxy, Zeenea, Collibra.
Usage management
When audit logs are available, observed usage is integrated into the repository and then exposed in the catalog. Users can thus tell “live” flows, consumed by tools or queried, from unconsumed flows and objects (often more than 80% of the total).
Typical use case: identify in the data catalog the objects that are candidates for rationalization or decommissioning.